Understanding how databases store table data such as rows and columns on disk forms the foundational groundwork for understanding how databases work internally. It helps us understand how indexes operate, how multi-level indexes are structured, and how B-trees and B+ trees efficiently store and access indexed data.
Let’s see how it works below for HDDs, and then the similar concept applies to the SSDs (covered in How SSDs Store Data).
Disk and Disk Structure
A disk is a non-volatile storage device used to store data persistently. Because it is non-volatile, the data on disk remains intact even when the system loses power (unlike RAM). This is why disks are essential for storing permanent files, databases, and operating system data.
Would highly recommend you watch this 3-minute YouTube video to get an idea of how an actual real HDD looks, so that you get a sense of what we are going to discuss in this article today.
The disk is composed of the following components:
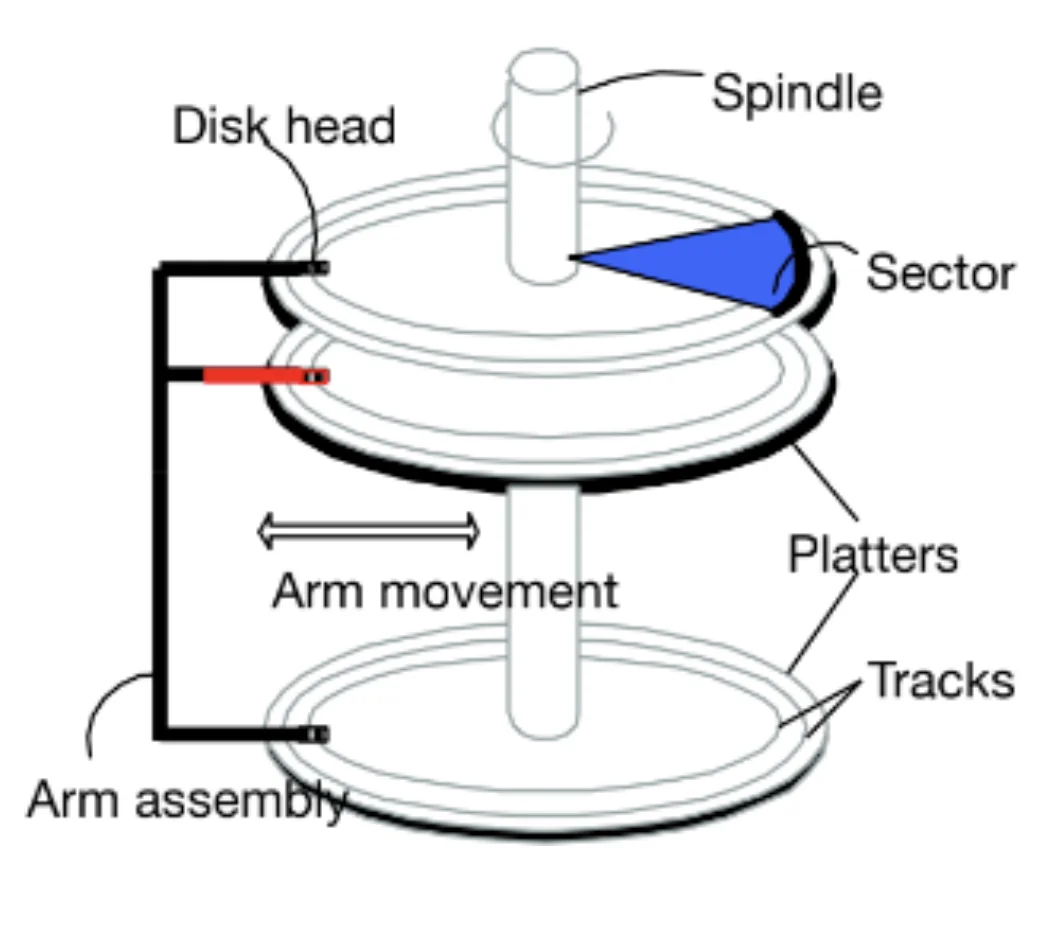
- Platters: Magnetic disks where data is recorded on both surfaces; and each surface is nothing but a set of concentric circles. (logic)
- Spindle (spindle motor): Rotates the spindle, which spins all the platters at a fixed RPM. (rotations per minute)
- Tracks: Individual concentric circular rings on the platter.
- Sector: This is a geometric sector, meaning just a portion of a disk. (shaped like a slice of pie.)
- Block (OS/filesystem block): The intersection of a track and a sector is called a block. Hence, any location on the disk, i.e., block address, can be identified by the track number and sector number. The block size is usually decided by the manufacturer. (earlier one block was around 512 bytes, now it is around 4KB+)
- Arm: Moves the read/write heads inward or outward to position them over the required track and sector.
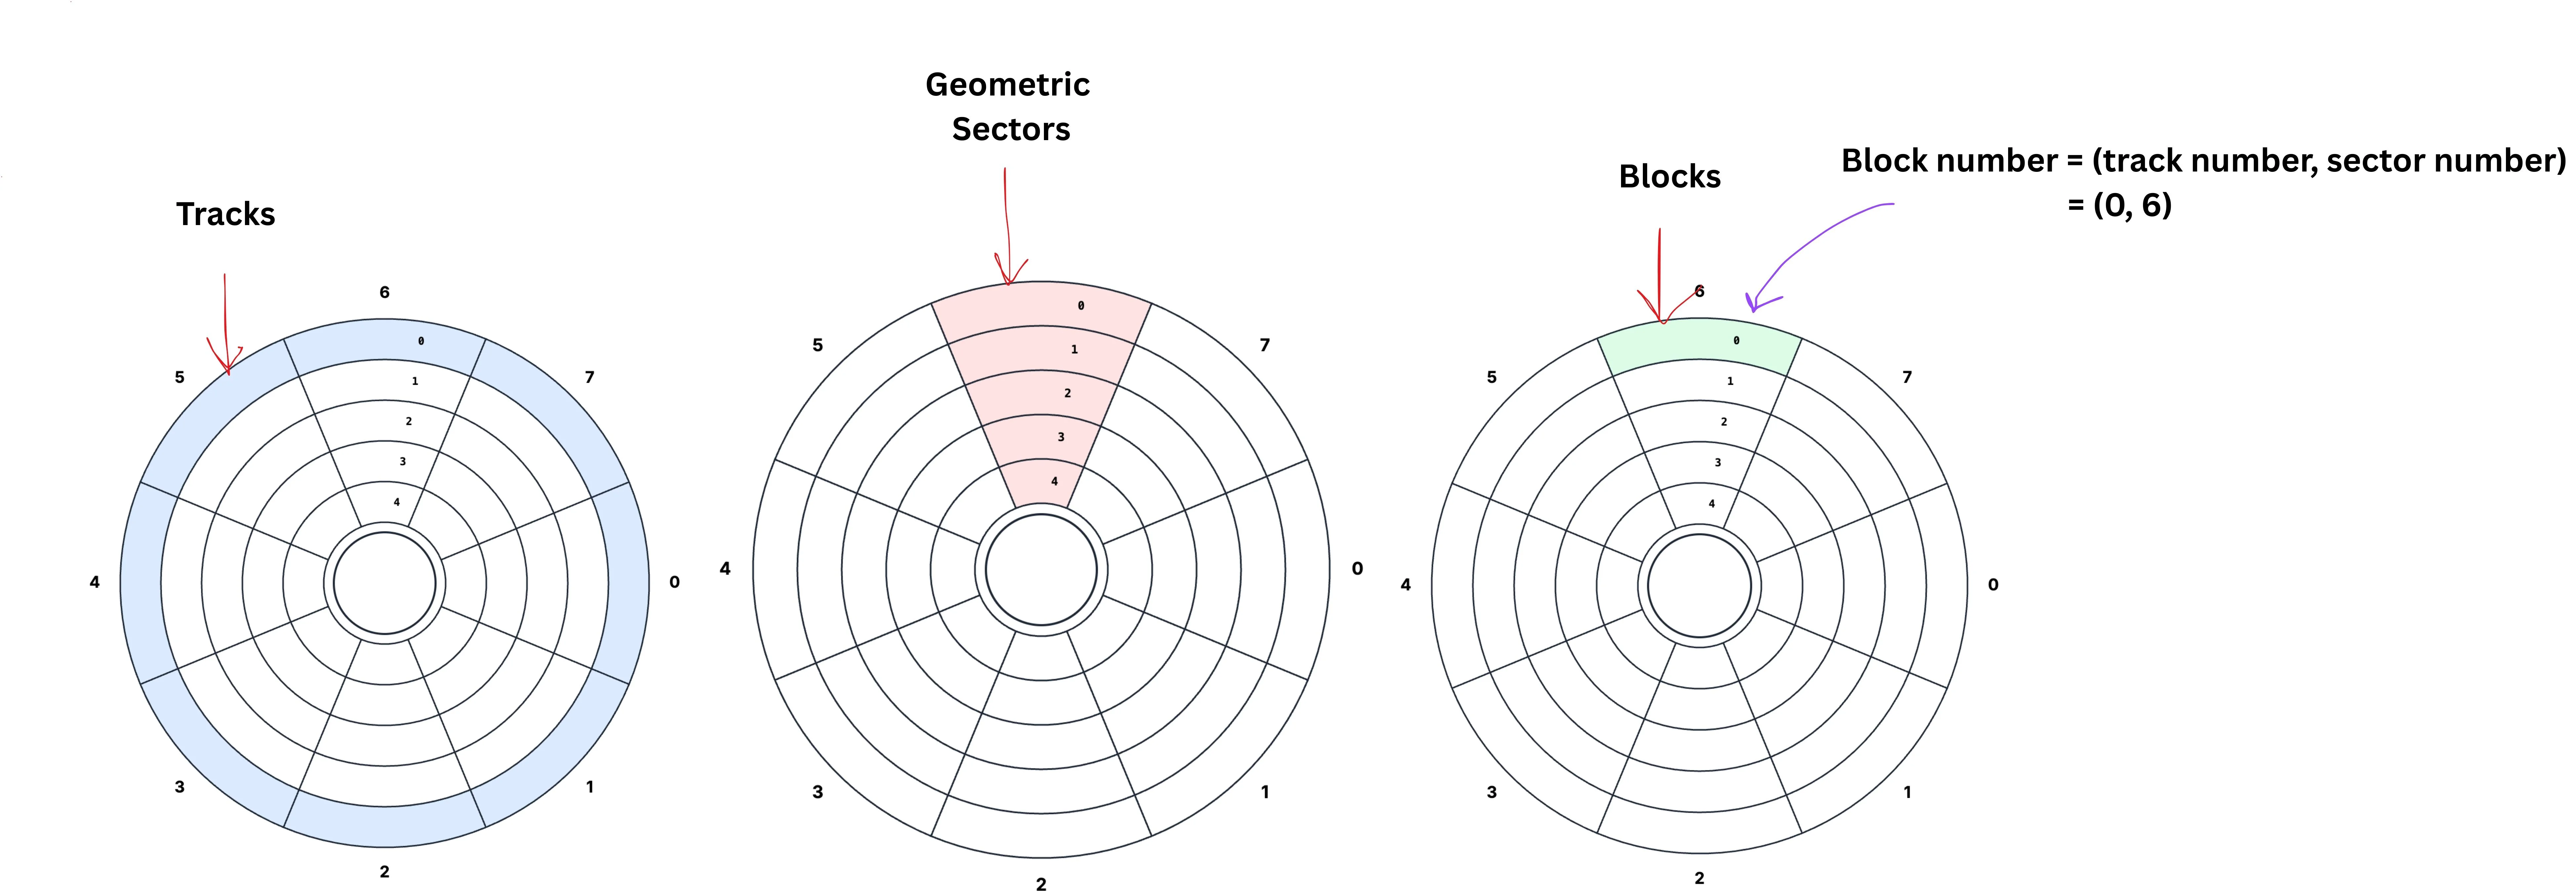
How data is accessed from the disk?
Question: So how do we access the disk to read and write?
Answer: Well, we use disk APIs, which are OS-level system calls like read() and write() to read data from disk and write data back to disk.
Question: But how much data is accessed at a time?
Answer: At the OS/filesystem level, it doesn’t like to deal with sectors etc, so data is transferred in blocks (usually 4 KB). Even if we ask for a few bytes, the OS typically returns the bytes that’s contained in those 4KB blocks. Meaning it is the minimum amount of data which can be read/write by an I/O operation.
At the database level, the DB does not like to deal with these blocks, it thinks its too small a unit, so it works with pages (e.g., 8 KB / 16 KB). A page is the DB’s logical unit, and it usually spans multiple blocks. So whenever we request data (using sql query for rows), the OS ends up fetching bytes from one block or a set of blocks (depending on how much we asked for). Meaning if the disk returns bytes from 2 blocks say 8KB, then the db considers it as 1 page of 8KB. (Let’s solve an example together to get a clear understanding of this..)
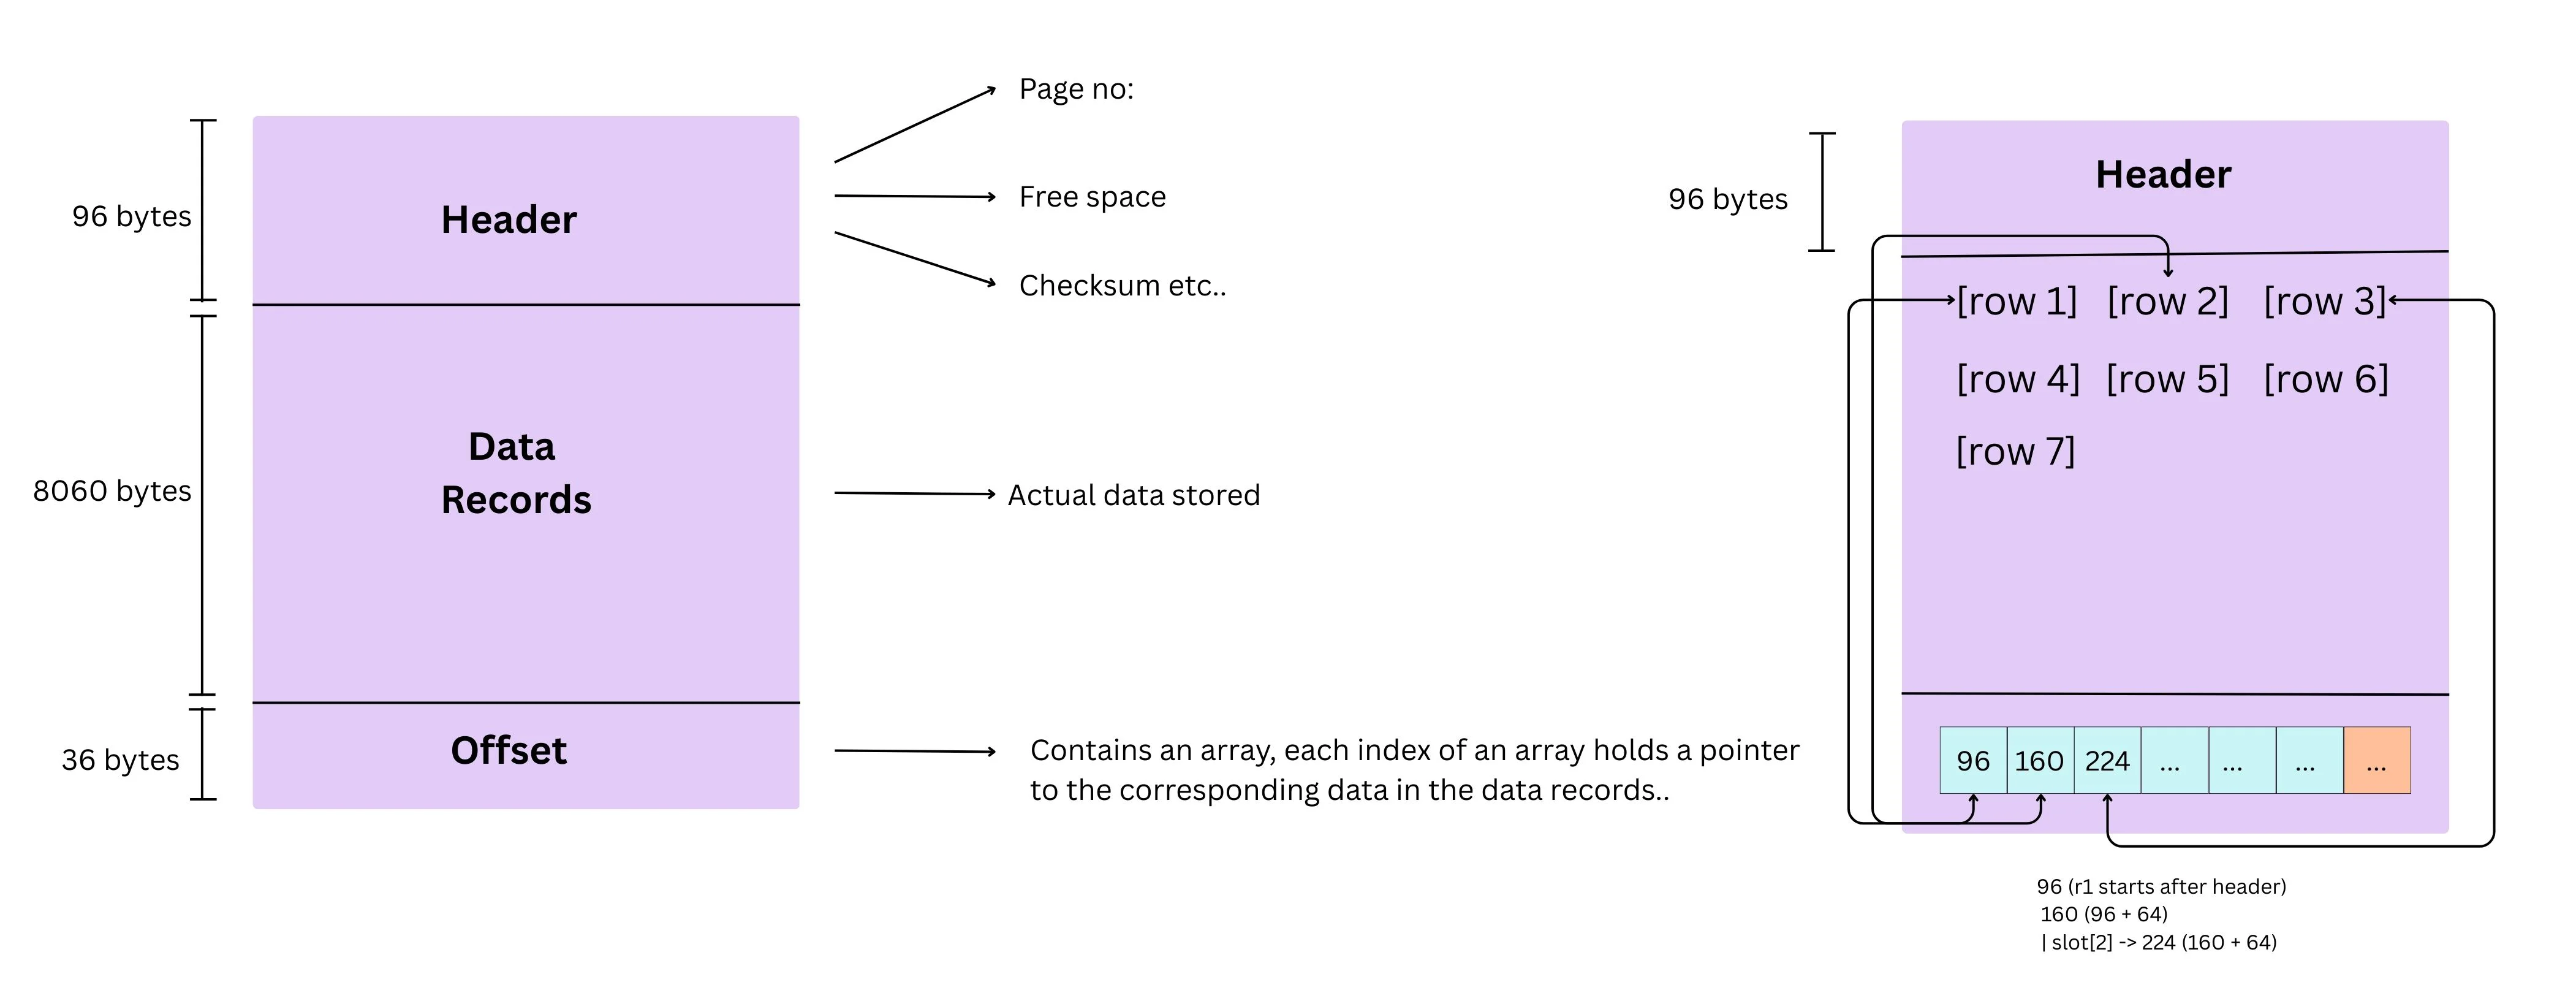
As discussed, a data page is a fixed-size chunk (e.g., 8 KB) that the database reads from disk into memory. If the underlying disk block size is 4 KB, then one 8 KB page is stored across two disk blocks, so the OS reads two blocks to bring one page into RAM.
- The page starts with a header that stores metadata like page id and free space pointers.
- Actual rows are stored sequentially in the data area as bytes.
- At the bottom of the page is a slot directory, which is an array of offsets. Each slot entry stores the byte position where a particular row begins inside the page.
Question: But after accessing the data where are we transferring it and storing it?
Answer: The data that’s read (the block/blocks) is first brought into our working memory (RAM). From there, the CPU can process it efficiently. And you might know that inside our working memory, we organize and manipulate that data using data structures. (arrays, hash maps, trees, etc.).
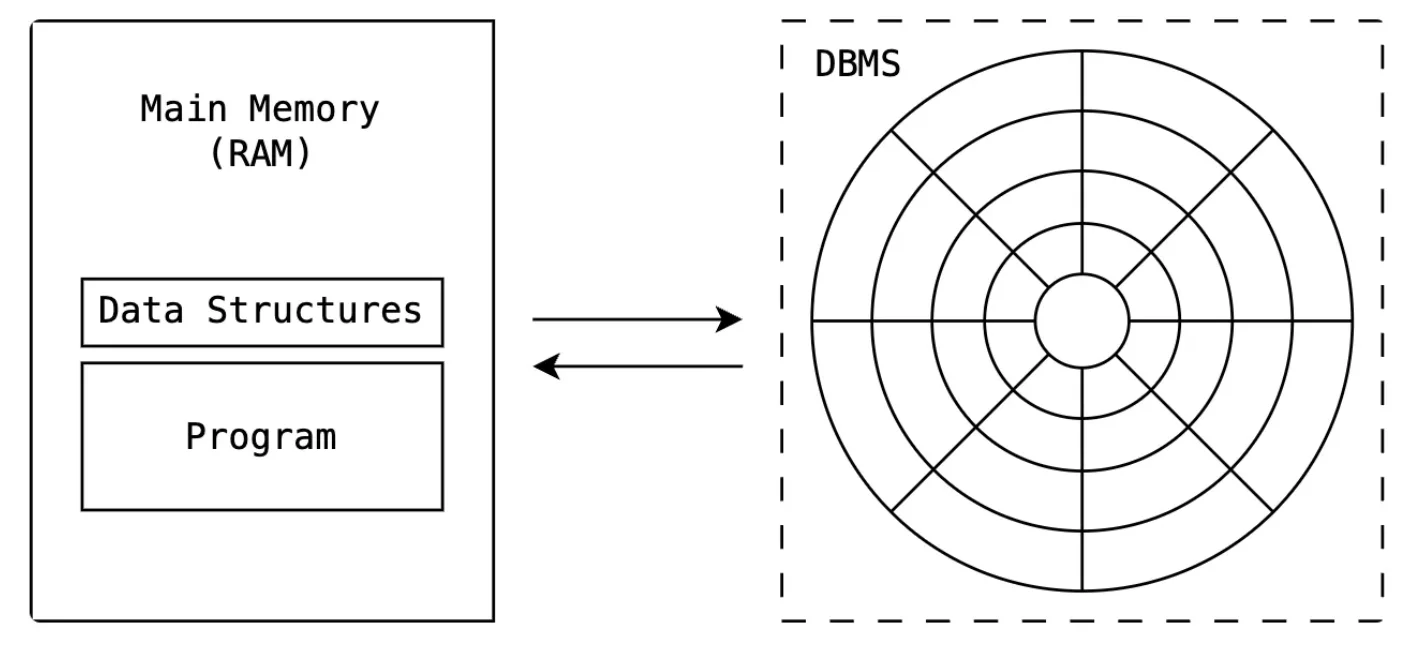
High level flow of how data flows in and out
Let’s try and put everything together and understand the high level flow of how data flows in and out.
Read Path
- DB finds the page where the rows live and identifies offset on disk for those rows. (If an index exists, the database uses the index to directly identify the page containing the row. If no index exists, the database scans pages sequentially until it finds the row.)
- DB asks the OS to read the bytes from that page file from certain offset till a certain offset.
- OS checks filesystem cache; if missing, OS reads from disk and returns to the db.
- DB places the page into the buffer pool (main memory) and reads the rows from that page.
Write Path
- DB finds the page where the rows live and pulls it into the buffer pool.
- DB updates the row in memory.
- DB writes a journal/WAL entry and persists it to disk
- The page stays in memory and may receive more writes before being flushed back to disk later (reducing I/Os)
- Inserts/deletes follow a similar pattern (details vary)
How data is organized on a disk with an example
Let’s consider our block size of the disk designed by our manufacturer to be 4KB. And the data page size of our database to be 8 KB. And we have a table of employee records containing 1000 records like this:
Employee id      → 16 bytes
Employee Name    → 16 bytes
Employee Address → 32 bytes
Total bytes of one row = 64 bytes
Now, say if we want to query and return one row (employee_id = 999):
SELECT * FROM employee_table WHERE employee_id = 999;We considered our page size to be 8KB right, with 8060 bytes being the empty record area.
one 8KB page = two 4KB blocks.
But since we are considering only 8060 bytes (as some bytes are taken away by header, and offset.. ), and 1 row is 64 bytes so:
Number of rows in 1 page = 8060 / 64
                         = 125.93
                         = 125 rows
So, one page will actually have 125 rows, and not 128 rows.
To cover all the rows, the total number of pages needed would be:
The total number of pages required = 1000 / 125
                                   = 8 pages
Rows are packed into pages; pages are fetched from disk using blocks. In order to fetch 8 pages in terms of OS level blocks:
The number of blocks to fetch 1 page = 8192 / 4096
                                     = 2 blocks
Each 8KB page is stored on disk across 2 contiguous 4KB blocks (meaning these 125 rows are spread across 2 sequential blocks). The OS reads those 2 blocks to get back the data to the page in memory
So searching for employee_id = 999 may require scanning all 8 pages (16 blocks), even though we need only one row.
This is the problem indexes solve. Continue with Database Indexing and Multi-Level Indexing to see how an index on employee_id cuts this down, and how multi-level indexes lead to B-trees.