This is a very common problem when dealing with neural networks.
When dealing with Sigmoid activation function activation function, one of the drawbacks is that it has vanishing gradient effect.
As we all know when a neural netowork learns, it works backwards (backward propagation) from output to input layer by layer. And during its backward propagation it learns the weights, parameters etc. based on the loss / gradient right.
Derivative of the Logits function:
Differentiating term by term:
Derivative of the sigmoid function:
Since , we can write this more simply as:
As, we found:
Compare that to what we just got:
These two are exact reciprocals of each other one is , the other is . This isn’t a coincidence, and it isn’t specific to logit and sigmoid, it’s a general calculus rule that applies to any pair of inverse functions.
Now, when backprop works its way back to a weight , it’s not computing directly in one shot it breaks it apart using the chain rule, since affects the loss only through a chain of intermediate steps () because :
- changes → this changes (since )
- changes → this changes (since )
- changes → this changes (since is computed from )
The middle term , the sigmoid’s derivative is the one we need to look closely at, because it’s the piece that misbehaves.
Plotting it out
Let’s compute at a few points along (the logit) and see what happens:
| 0 | 0.500 | 0.250 |
| 1 | 0.731 | 0.197 |
| 2 | 0.881 | 0.105 |
| 3 | 0.953 | 0.045 |
| 4 | 0.982 | 0.018 |
| 6 | 0.998 | 0.002 |
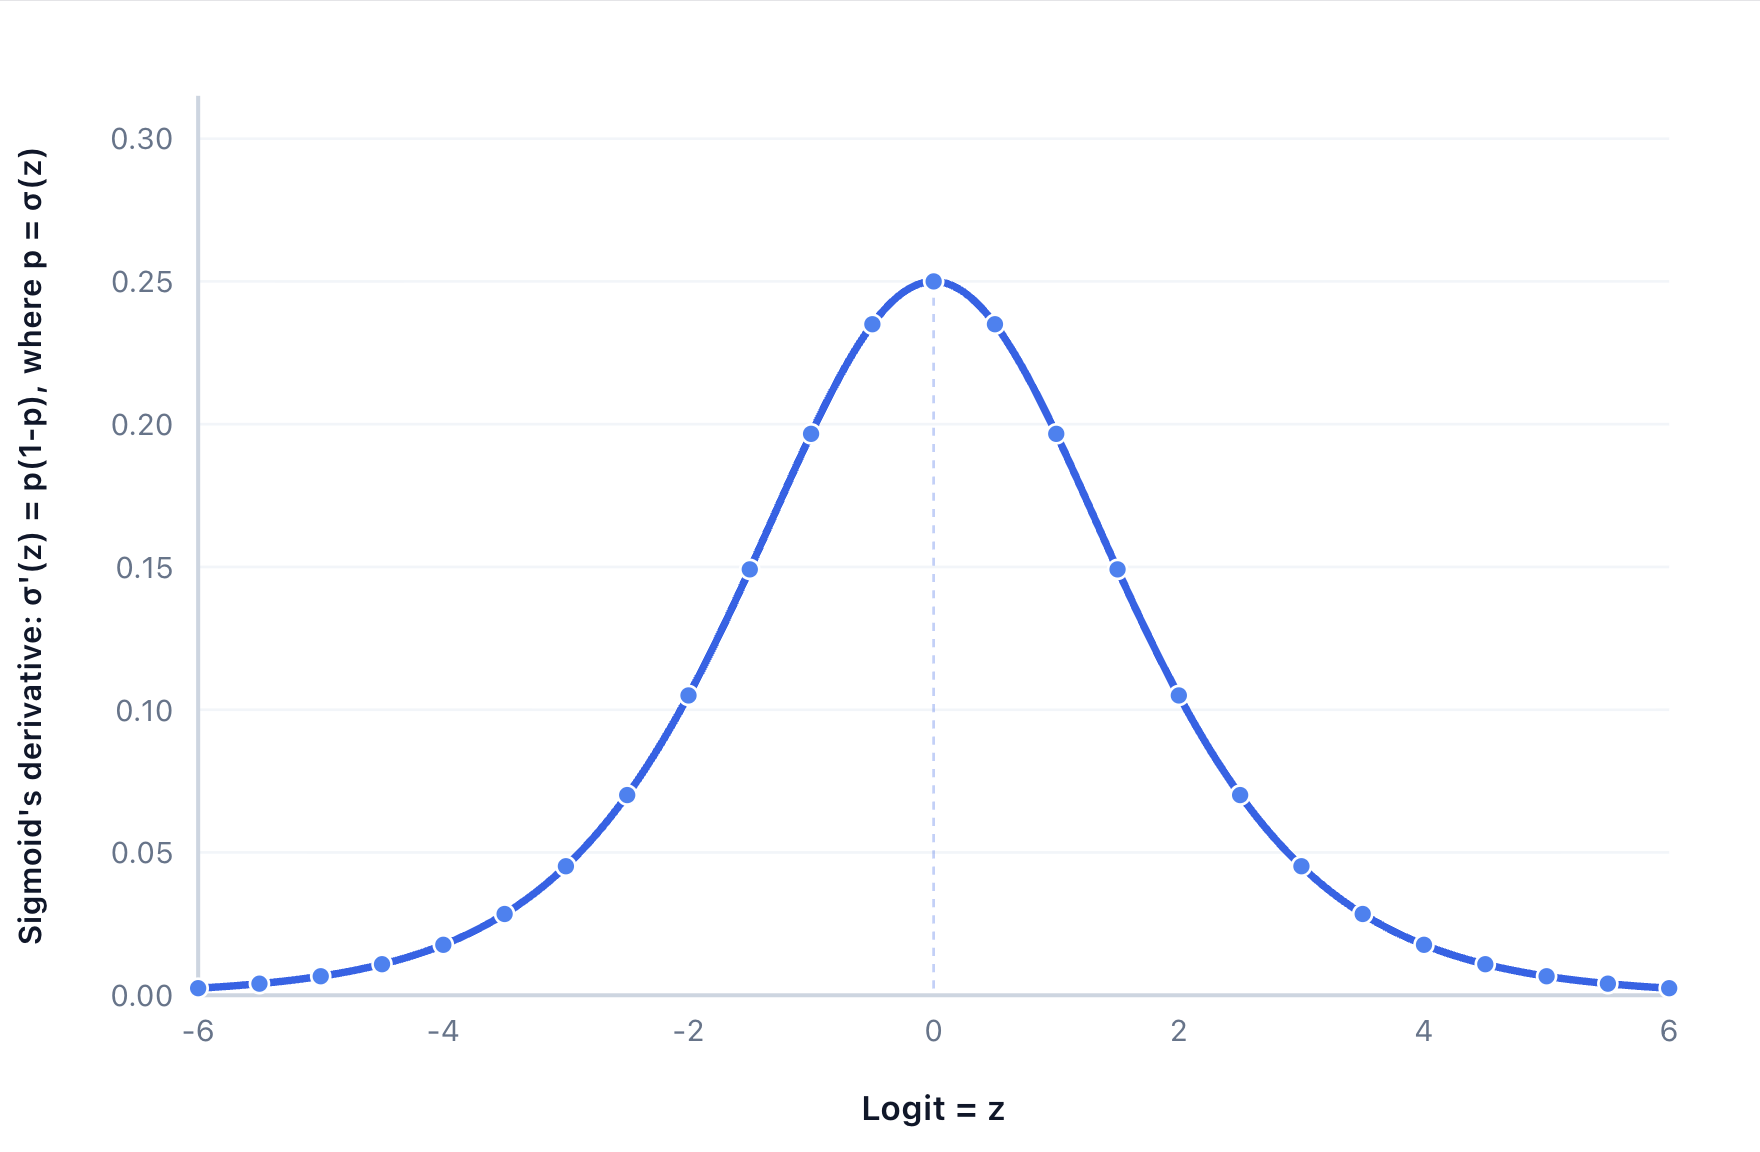
Look at the shape: it peaks at just 0.25 at , and rapidly flattens toward 0 as moves toward either or .
This curve above shows the behavior of a single neuron, at a single layer. It tells that if this neuron’s logit is far from 0 (i.e., around -6, 6 or more), then its local gradient is tiny. hence this is called saturation.
As the number of layers increase, say if there are 10 layers then :
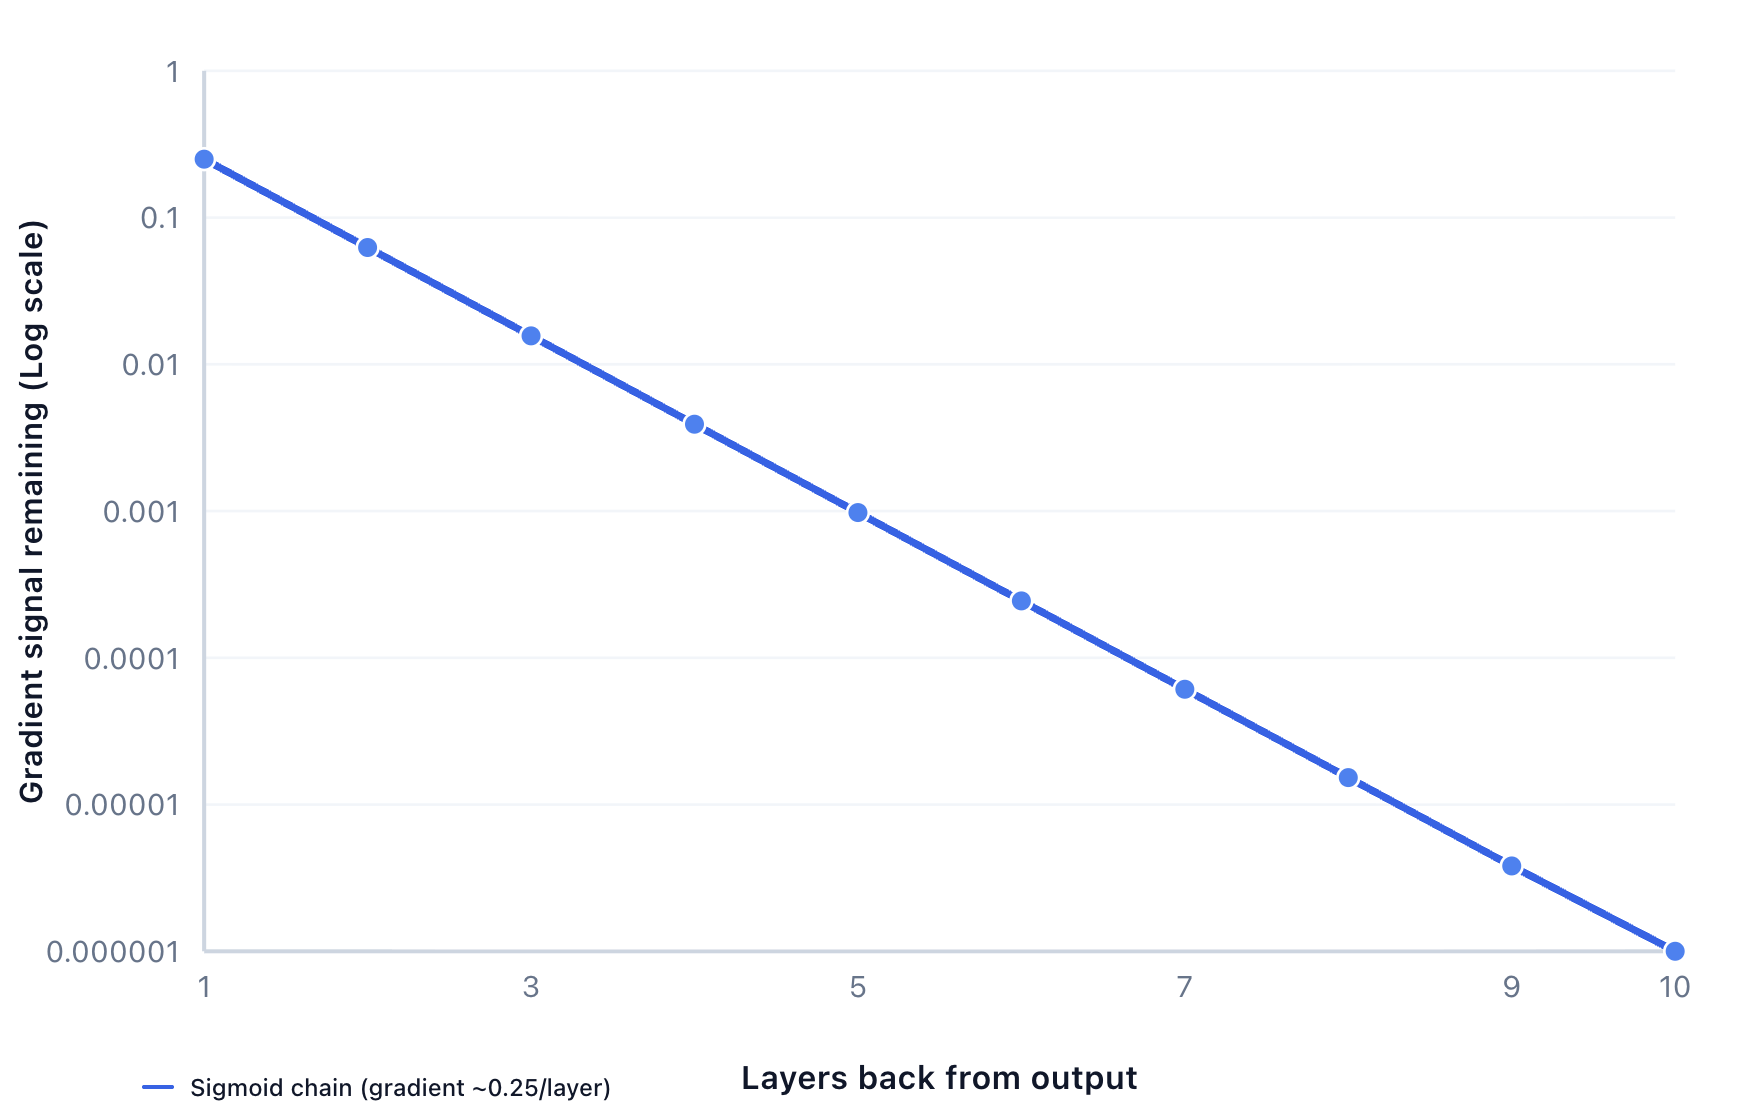
Vanishing gradient is what happens when you chain many of these together across depth. Backprop multiplies the local gradients of every layer together as it works backward. So that network stops learning, or learns extremely slowly.